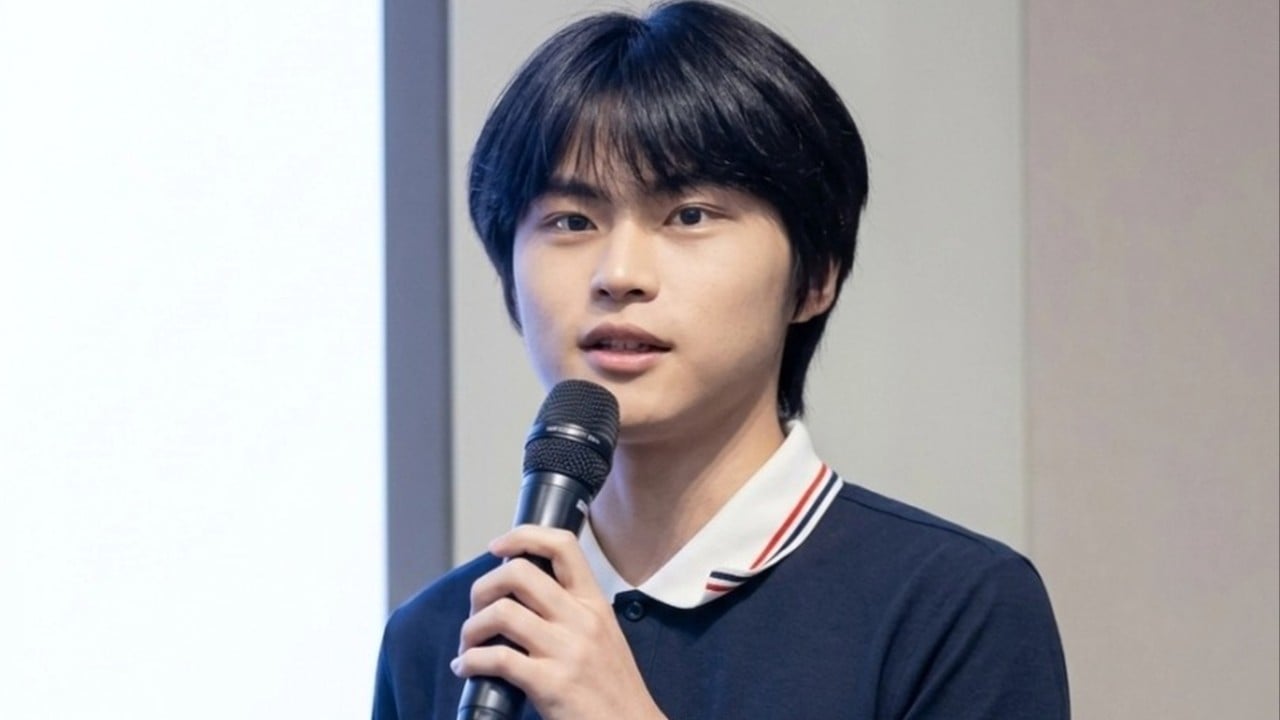
Rumors linking 17-year-old researcher Nathan Chen Guangyu to Discovery Loop expose a structural collision in frontier artificial intelligence: high-velocity architectural talent from Moonshot AI intersecting with a public benefit company engineered to automate scientific discovery. Conventional coverage treats this move as a celebrity prodigy story—a teenager leaving Kimi (Moonshot AI) for a startup founded by former Google luminaries. That framing mistakes surface-level biographical novelty for underlying market mechanics. To understand what is actually happening, the analysis must separate verified organizational facts from speculative rumor, map the incentives of both sides, and evaluate how research velocity scales inside an automated experimentation lab.
Deconstructing the Competitor Narrative
Typical rumor-driven articles follow a predictable three-step template. First, they inflate age into an implicit proof of genius, highlighting that Chen worked on models at Moonshot AI at 16 and 17. Second, they pair the prodigy hook with star power at the destination, pointing to heavyweight founders leaving Google to build a new venture. Third, they treat unconfirmed destination reports as settled destiny while glossing over how a neural architecture specialist fits into a scientific automation company.
This narrative misses three cause-and-effect relationships:
- Credentialing versus execution: A teenage co-first author on a technical report proves rapid pattern recognition and engineering output under tight iteration loops, not automatic alignment with every research regime. High-output contributors thrive when problem boundaries are crisp and feedback cycles are fast; moving across continents and research paradigms introduces onboarding friction that can temporarily depress raw output.
- Model architecture versus experimental loops: Core model design—such as attention mechanisms or residual connections—optimizes representation learning and training dynamics. Automating the scientific method requires closing a broader loop: hypothesis generation, parallel experiment execution, physical or simulated measurement, and state updating across thousands of trials. Those are adjacent engineering problems, not identical ones.
- Rumored alignment versus actual placement: Talent markets in frontier AI move faster than public confirmation. Rumors frequently conflate active recruiting interest, relocation announcements, and conflicting reports about where an engineer actually lands.
Verified Facts Versus Educated Hypotheses
Rigorous strategy requires drawing a hard line between documented facts and analytical inference. When exact equity terms, compensation packages, or internal team assignments are undisclosed, pretending to know them degrades credibility. Instead, the mechanics of the move can be evaluated through verifiable anchors and structural hypotheses.
Known Facts
- Discovery Loop's corporate form and mission: Discovery Loop launched in 2026 as a public benefit corporation focused on automating the experimental loops of science and engineering through parallel experimentation.
- Founding leadership pedigree: The founding team includes Jeff Dean, Sanjay Ghemawat, Quoc Le, and Oriol Vinyals—veterans known for large-scale distributed systems, systems engineering, and machine learning research.
- Nathan Chen Guangyu's trajectory: Chen (known on X as Nathan Chen) entered Moonshot AI as an intern at age 16, co-authored the Attention Residuals technical report as a joint first author, and announced his departure from Moonshot AI in October 2026 alongside reports of a move to the United States.
- Competing and conflicting reporting: October 2026 coverage linked Chen to Discovery Loop, while separate reports also circulated regarding Anthropic, underscoring that public rumor trails internal hiring decisions.
Educated Hypotheses
- Why a scientific-automation lab attracts model-architecture talent: Even if a company's core thesis is automating scientific discovery, parallel hypothesis testing at scale still relies on strong reasoning, code or experiment synthesis, and efficient model architectures. Engineers who can squeeze higher signal out of residual pathways or attention designs directly improve the cognitive engine driving the loop.
- Why public benefit governance shapes recruiting: A public benefit structure signals long-horizon scientific value alongside commercial viability. For researchers tired of pure consumer-product churn, a mission-oriented lab with deep systems infrastructure offers a distinct value proposition compared to standard commercial labs.
The Three Pillars of Discovery Loop's Operating Model
To evaluate why a company like Discovery Loop sits at the center of frontier talent speculation, break its operating model into three functional pillars. Each pillar carries a distinct engineering bottleneck and economic logic.
1. Parallelized Hypothesis and Experimentation Engine
Traditional scientific workflows are serial and bottlenecked by human bandwidth. A researcher formulates a hypothesis, designs an experiment, waits for execution or lab results, interprets noise, and adjusts. Discovery Loop's stated thesis centers on deploying AI systems that run thousands of experiments in parallel to automate that loop.
Mechanically, parallelization only pays off if experiments are independent enough to batch yet informative enough to prune the search space. Running ten thousand low-signal trials wastes compute and laboratory capacity if the scoring function cannot separate real signal from systematic error. The core technical challenge is active learning under budget constraints: allocating the next batch of trials where expected information gain per unit cost is highest.
2. Systems Infrastructure and Execution Throughput
Parallel proposals mean very little without infrastructure that schedules, isolates, monitors, and aggregates thousands of runs without cascading failures. This is where deep systems engineering pedigree becomes a decisive moat rather than a resume ornament.
High-throughput experimentation creates three classic systems failure modes:
- Resource contention and stragglers: A small fraction of slow or hung experiments can stall synchronous batch updates, turning theoretical parallelism into serialized waiting.
- State and provenance drift: When thousands of automated runs mutate parameters or datasets continuously, irreproducible state makes debugging experimental anomalies nearly impossible.
- Evaluation reward hacking: Automated loops optimize whatever metric is wired into the objective function. Without strict verification and out-of-distribution checks, the system can exploit simulation artifacts or proxy metrics instead of advancing real scientific ground truth.
3. Capital Structure and Talent Gravity
Frontier AI talent markets operate under power-law dynamics. A tiny fraction of researchers and systems architects can unlock disproportionate leaps in throughput or model efficiency. Recruiting top talent requires matching three variables to the candidate's stage: compute access, autonomy over research direction, and upside alignment.
A public benefit corporation backed by prominent venture and institutional capital—and led by recognizable technical founders—solves a specific recruiting problem: credibility at inception. Early-stage startups usually force candidates to trade stability for upside. A founder group with decades of systems and AI track record compresses perceived execution risk while preserving startup speed.
The Cost Function of Prodigy Talent Mobility
Hiring a teenager who has already shipped influential architectural work at a major AI lab looks like a pure win on paper. In practice, every talent transfer carries a cost function across onboarding, knowledge transfer, and organizational fit.
The first term in that cost function is context loss. Work inside an existing lab—such as contributing to Attention Residuals and seeing those ideas carry into subsequent model generations—benefits from accumulated codebase familiarity, internal benchmarks, and established team norms. Moving to a new organization resets much of that tacit context.
The second term is integration overhead. Young researchers who excel in fast-moving model teams often thrive on tight feedback loops and high individual ownership. Placing them into a nascent or heavily systems-driven lab only compounds output if their strengths map cleanly to an immediate bottleneck—such as training stability, reasoning efficiency, or rapid prototyping of search and proposal models.
The third term is signaling noise. Media coverage often treats a prodigy's move as a verdict on the old employer's weakness or the new employer's supremacy. Usually, it reflects individual career optimization: seeking new problems, geographic relocation, mentorship access, or higher leverage at a formative stage.
Four Operational Lessons for Research Leaders and Strategists
Whether you are evaluating AI startups, building a technical team, or covering frontier labs, four operational rules emerge from this dynamic:
- Audit the bottleneck before celebrating the hire. Ask what specific constraint limits the organization today—compute scheduling, experimental verification, data generation, or model reasoning—and check whether the incoming talent directly relieves that constraint.
- Separate public rumor from verified commitment. In fast-moving research circles, exploratory talks, relocation plans, and competing reports often overlap. Anchor analysis on confirmed organizational roles and shipped technical work rather than rumor velocity.
- Measure loop cycle time, not headcount. For an automated discovery company, competitive advantage depends on how fast a cycle of hypothesis, execution, and verification completes—and how accurately results transfer to reality—rather than how famous the roster looks.
- Design mentorship and scope intentionally for early-career outliers. High-velocity young engineers burn out or stall when trapped in bureaucratic layers or vague mandates. Pair high autonomy with clear technical milestones and strong systems mentorship.
Limitations and Analytical Blind Spots
No single framework captures every variable in frontier AI. External observers face structural blind spots around proprietary roadmaps, internal hiring timelines, and unpublished benchmarks. Furthermore, automating scientific discovery faces physical and empirical limits that pure software scaling cannot erase: real-world experiments still face physical constraints, measurement noise, regulatory hurdles, and domains where ground-truth validation is slow or expensive. High pedigree and clever model architectures lower friction, but they do not repeal physical laws or experimental validation costs.
Strategic Play
For technical leaders and investors watching Discovery Loop and high-velocity researchers like Nathan Chen Guangyu, the winning play is betting on closed-loop verification over isolated model hype. Do not evaluate an AI-for-science venture merely by the fame of its founders or the youth of its recruits; evaluate whether its architecture pairs strong generative proposals with rigorous, automated experimental feedback that prevents self-deception at scale. If you are building or advising a research organization, prioritize tightening your hypothesis-to-verification loop and protecting high-leverage builders from organizational drag—because in automated discovery, the team that compounds verified signal per unit of time wins.